
Token Embeddings
See how a token ID becomes a learned vector: the lookup that turns identifiers into numbers a transformer can compute with.
Token Embeddings: The Book Behind the Call Number
A token ID is a library call number: it only tells you where to look. The embedding is the book you bring back — a long list of learned numbers. The transformer reads those books together to work out how each word is being used in the sentence.
IntroductionWhat is a token embedding?
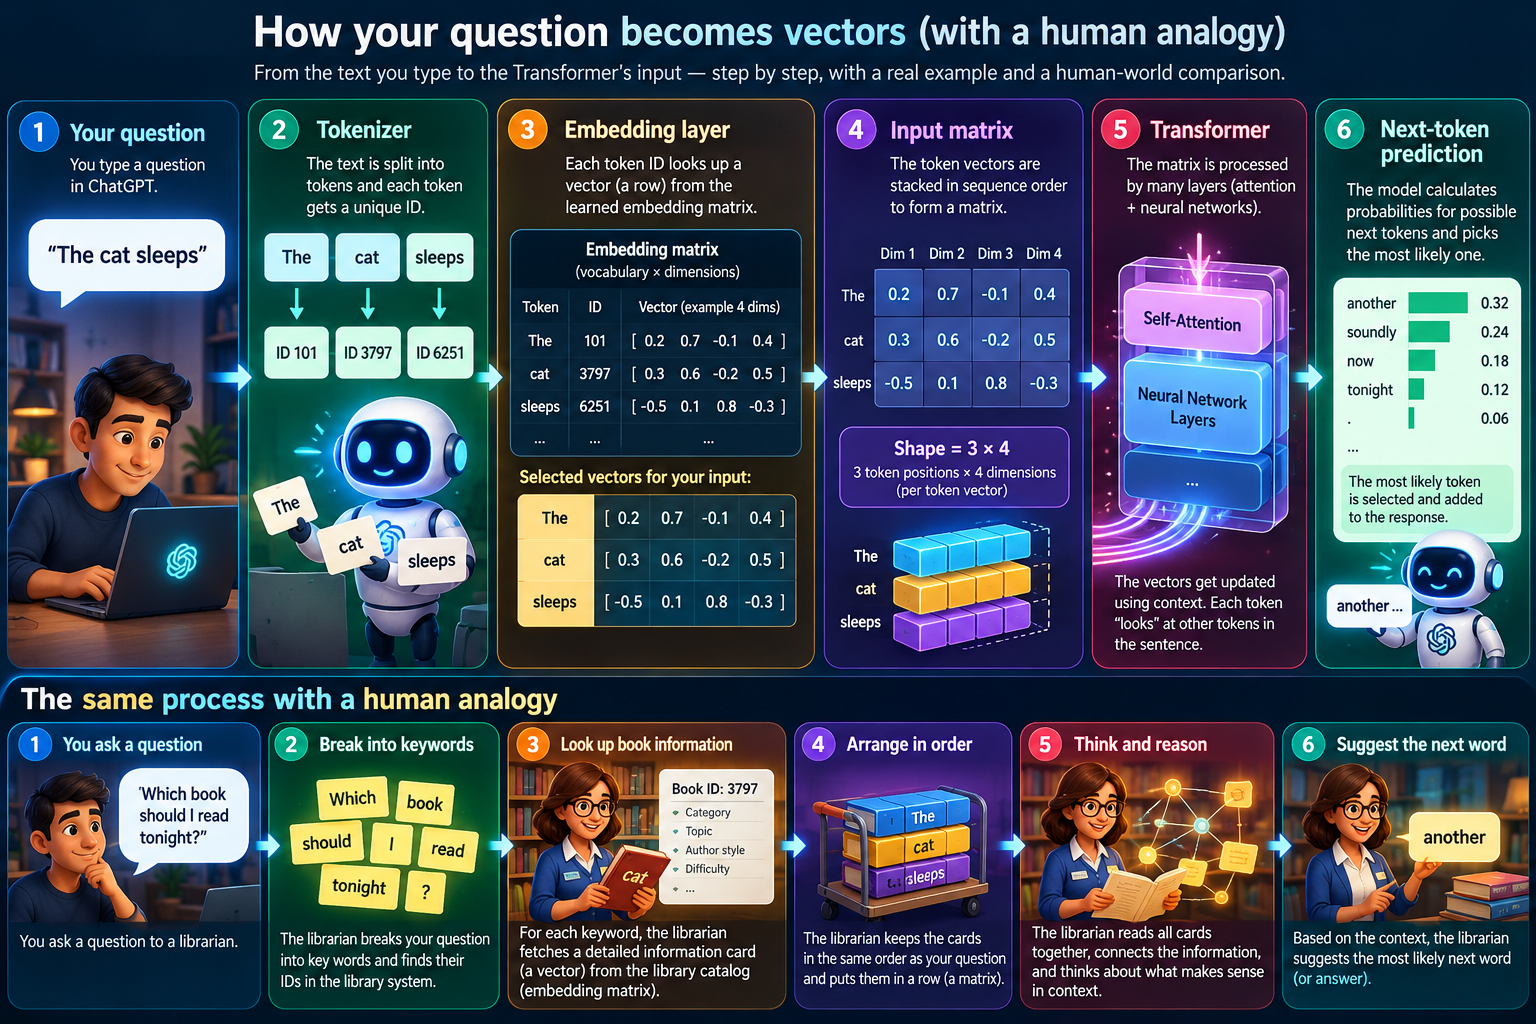
"Once my sentence has been turned into token IDs, does the AI finally know what I said?"
Not yet. After tokenization the model holds a list of integers — barcodes. It still has to turn each barcode into a vector before a transformer can compute anything with it.
3797 is only a name. The model uses it as a row number, reads that row of a big learned table, and gets back a list of numbers such as [0.21, -0.43, 0.87, …]. That list is the token embedding — the first thing the transformer can actually compute with.
A token embedding is the learned vector that a model assigns to one entry of its vocabulary. The model reads it from the embedding matrix by using the token ID as a row index.
💡 Tokenization gives identifiers; embedding gives vectors. Token IDs tell the model which token it is looking at. Embeddings are what the transformer can meaningfully process.
WhyWhy can't the transformer work directly with token IDs?
A token ID is just an integer used to identify a token in the model's vocabulary. For example (illustrative IDs):
cat→ token ID3797dog→ token ID8531
The numbers themselves don't inherently express meaning. The ID for dog being larger than the ID for cat does not mean a dog is more important, bigger, or more similar to a cat. The numbering follows the order in which the vocabulary was built — nothing more.
What goes wrong with raw IDs
- Arithmetic on IDs has no meaning:
8531 − 3797 = 4734describes nothing about cats or dogs. - A linear layer would treat ID 8531 as "bigger" than ID 3797, inventing a false ordering.
- Nearby IDs are not related words; related words can have far-apart IDs.
What the transformer needs
- Numbers that can take part in meaningful maths: dot products, sums, projections.
- A geometry in which "similar" tokens can end up close together.
- Values that training can adjust with gradients.
IntuitionFrom call number to the book itself
The Token IDs page used a library analogy: an ID is a call number. This page continues it.
- Tokenization hands the model a slip of paper with call numbers:
[464, 3797, 318, 10447]. - Embedding lookup is the trip to the shelf. The call number is only used to find the right spot; what comes back is the book — a long learned vector.
- The transformer is the scholar who reads those books together and works out how each one is being used in this particular sentence.
Two tables, one ID
A token ID works like a row ID. The same number is used as the key into two different tables. (Small IDs below are illustrative.)
Table 1 — Vocabulary (tokenizer)
| Token ID | Token |
|---|---|
| 0 | the |
| 1 | cat |
| 2 | dog |
| 3 | bank |
| 4 | river |
Maps token ↔ ID. Text the cat becomes [0, 1].
Table 2 — Embedding matrix E (model)
| Row | Vector (illustrative) |
|---|---|
| 0 | [ 0.2, 0.5, −0.1, …] |
| 1 | [ 0.8, −0.3, 0.4, …] |
| 2 | [−0.2, 0.7, 0.1, …] |
| 3 | [ 0.1, 0.6, −0.5, …] |
| 4 | [ 0.0, 0.4, −0.6, …] |
Maps ID → learned vector. ID 1 selects row 1: the vector for cat.
- The vocabulary is a dictionary-like mapping (
"cat" → 1), usually a hash map, and often supports ID → token as well. - The embedding matrix is not a dictionary. It is a dense array indexed by position,
E[1]. It stores no token strings. - They are aligned only by the shared number. Row i of E belongs to token i because training used that alignment. Change the tokenizer and every ID points at the wrong row.
- Row count vs vocabulary size: usually one row per vocabulary entry, though some models pad E with extra rows.
Does a token ID contain the vector numbers?
No. The ID only says which row to read. Take token ID 1 (cat) from the tables above, with a 4-number row (illustrative values):
The ID 1 is not the vector [0.80, −0.30, 0.40, 0.15]. It is the address used to retrieve it.
Where do the vector numbers come from?
- Start: the embedding values are typically initialized with a numerical initialization scheme, so at first they carry no useful meaning.
- Training: the model adjusts them through optimization and backpropagation (see phase 04).
- Result: over time the values become useful for the model's language-processing task. A real LLM stores hundreds or thousands of numbers per token.
Remember: token ID = which row? Vector = the learned numbers stored in that row.
💡 The ID is the key; the vector is the content. Think of a token ID as a database row index, not as the meaning of the word.
💡 Critical mental model: before the lookup the model "knows" nothing about the words. After the lookup it holds learned numbers. After the transformer layers it holds numbers that also reflect the surrounding words.
TheoryWhat does the model know at each stage?
It is tempting to say "the model learns the meaning at the embedding step". That is not quite right. The embedding step only reads parameters that were already learned during training.
| Stage | What exists | What it can express |
|---|---|---|
| After tokenization | Discrete token IDs | Identifies tokens. The integers themselves carry no usable numeric geometry. |
| After embedding | One learned vector per token | A numeric representation the transformer can process. It is the same vector for a token wherever it appears. |
| After transformer layers | Context-updated vectors | How each word is being used in this sentence (see Contextual Embeddings). |
Where the knowledge actually lives
- The embedding matrix and the transformer weights were established during training.
- At inference the model uses those fixed parameters to process your input. It does not suddenly acquire knowledge at the embedding stage.
- The embedding matrix typically starts with random values and is adjusted by backpropagation until related tokens end up with useful vectors.
How It WorksThe four-step pipeline, with a lookup in the middle
Follow "The cat is sleeping" through the pipeline:
The cat is sleeping[464, 3797, 318, 10447]. Illustrative IDs; actual IDs depend on the tokenizer.[0.21, -0.43, 0.87, ...] for cat.
graph LR
    A["Text: The cat is sleeping"] --> B["Token IDs: 464, 3797, 318, 10447"]
    B -->|"row lookup in E"| C["4 vectors, each D numbers"]
    C --> D["Transformer layers"]
    D --> E["Contextual representations"]

    style A fill:#3b82f6,stroke:#1d4ed8,color:#fff
    style B fill:#10b981,stroke:#047857,color:#fff
    style C fill:#8b5cf6,stroke:#6d28d9,color:#fff
    style E fill:#f59e0b,stroke:#b45309,color:#fff
CalculateManual lookup with a tiny 4-dimensional matrix
Real models use hundreds or thousands of dimensions. Here we use 4 so every number fits on the page. The vectors are invented for teaching; they are not from a trained model.
E[464] = [ 0.10, −0.05, 0.02, 0.30] "The"E[3797] = [ 0.21, −0.43, 0.87, 0.15] "cat"E[318] = [ 0.05, 0.02, −0.04, 0.22] "is"E[10447]= [−0.30, 0.55, 0.40, −0.10] "sleeping"E[8531] = [ 0.25, −0.40, 0.80, 0.10] "dog"
[464, 3797, 318, 10447] select four rows, producing a 4 × 4 matrix (sequence length × embedding dimension).4734 and |3797 − 318| = 3479. By ID distance, "cat" looks closer to "is" than to "dog".cos(cat, dog) =
0.997 — nearly the same directioncos(cat, is) =
0.000 — unrelated direction
What does "dimension" mean?
Dimension is how many numbers are inside one token's vector. Using cat from Step 1 (illustrative values):
Each dimension is one position in the vector. Together the numbers form the token's learned numerical representation. Language has many patterns and relationships, and a single number would give the model very little capacity to represent them.
A human analogy
Describing a person
- Height: 175 cm
- Age: 30 years
- Weight: 70 kg
- Shoe size: 9
[175, 30, 70, 9] → 4 measurements = 4 dimensions.
Describing the token "cat"
- Dim 1: 0.21
- Dim 2: −0.43
- Dim 3: 0.87
- Dim 4: 0.15
[0.21, −0.43, 0.87, 0.15] → 4 learned numbers = 4 dimensions.
- Person → the thing being represented (here: the token).
- Measurements → the individual dimensions.
- List of measurements → the vector.
- Number of measurements → the dimensionality.
How big are vectors in real models?
| Example embedding dimension | Numbers per token |
|---|---|
| 4 (this page's toy example) | 4 |
| 128 | 128 |
| 768 | 768 |
| 4,096 | 4,096 |
| 12,288 | 12,288 |
These are example sizes; actual models vary. With 4,096-dimensional embeddings, each token ID retrieves a vector of 4,096 numbers. For a matrix with 50,000 tokens and 4,096 dimensions, the shape is 50,000 × 4,096: 50,000 rows, each containing 4,096 numbers.
A more detailed person description can capture more detail, and likewise more dimensions can represent more. But more dimensions alone do not guarantee a better model; architecture, training and the learned parameters matter too.
MathematicsThe lookup as row selection
Let $V$ be the vocabulary size and $D$ the embedding dimension. The embedding matrix is
For a token ID $i$, its embedding is row $i$:
$$\mathbf{e}_i = \mathbf{E}[i, :] \in \mathbb{R}^{D}$$For a sequence of $L$ token IDs, the transformer receives:
$$\mathbf{X} = \mathbf{E}[[i_1, \ldots, i_L]] \in \mathbb{R}^{L \times D}$$Same thing as a one-hot matrix product
If $\mathbf{o}_i \in \{0,1\}^{V}$ is the one-hot vector with a 1 at position $i$, then
So the lookup is mathematically a matrix product, but frameworks implement it as direct row indexing because multiplying by a mostly-zero vector would waste work.
Size
VisualizeDiagram and live ID-vs-vector comparison
Pick any two words. The lab compares what the IDs say with what the vectors say, using the toy 4-dimensional matrix from the Calculate phase.
CodeEmbedding lookup from scratch, then PyTorch
Part A — pure Python:
import math

vocab = {"The": 464, "cat": 3797, "is": 318, "sleeping": 10447, "dog": 8531}  # illustrative IDs

E = {   # toy 4-d "embedding matrix", keyed by token ID
    464:   [ 0.10, -0.05,  0.02,  0.30],
    3797:  [ 0.21, -0.43,  0.87,  0.15],
    318:   [ 0.05,  0.02, -0.04,  0.22],
    10447: [-0.30,  0.55,  0.40, -0.10],
    8531:  [ 0.25, -0.40,  0.80,  0.10],
}

def cosine(a, b):
    dot = sum(x * y for x, y in zip(a, b))
    return dot / (math.sqrt(sum(x * x for x in a)) * math.sqrt(sum(y * y for y in b)))

ids = [vocab[w] for w in ["The", "cat", "is", "sleeping"]]
print(ids)                       # [464, 3797, 318, 10447]

vectors = [E[i] for i in ids]    # the embedding lookup
print(vectors[1])                # [0.21, -0.43, 0.87, 0.15]

print(abs(vocab["cat"] - vocab["dog"]))            # 4734  (ID gap)
print(abs(vocab["cat"] - vocab["is"]))             # 3479  (ID gap)
print(round(cosine(E[3797], E[8531]), 3))          # 0.997 (cat vs dog)
print(round(cosine(E[3797], E[318]), 3))           # 0.0   (cat vs is)
Part B — PyTorch nn.Embedding:
import torch
import torch.nn as nn

emb = nn.Embedding(num_embeddings=50257, embedding_dim=768)   # E has shape [50257, 768]

ids = torch.tensor([[464, 3797, 318, 10447]])   # shape [batch=1, seq_len=4]
x = emb(ids)                                     # row lookup: weight[ids]
print(x.shape)                                   # torch.Size([1, 4, 768])

print(emb.weight.requires_grad)                  # True  -> the rows are learned parameters
print(emb.weight.numel())                        # 38597376
nn.Embedding holds random numbers. The useful geometry appears only after training (or by loading a trained model's weights).ExperimentProbe a real model's embedding matrix
Try these with a real tokenizer and model (for example gpt2 from HuggingFace):
CompareToken ID vs one-hot vs embedding vs contextual vector
| Property | Token ID | One-hot | Token embedding | Contextual vector |
|---|---|---|---|---|
| Type | Integer | Sparse vector, length V | Dense vector, length D | Dense vector, length D |
| Learned? | No (fixed by vocabulary) | No | Yes (rows of E) | Yes (produced by learned layers) |
| Depends on neighbours? | No | No | No | Yes |
| Similar tokens close together? | No | No (all equally far apart) | Can be, after training | Yes, and context-aware |
| Where it appears | Tokenizer output | Conceptual / math view | Transformer input | Every layer after the first |
ApplyWhere token embeddings show up in real models
- First layer of every language model: an integer tensor
[B, L]becomes a float tensor[B, L, D]. - Position is added separately. The lookup says nothing about word order; models add positional information (for example GPT-2 adds learned position embeddings) before the first transformer layer.
- Weight tying: many models, including GPT-2, reuse the input embedding matrix as the output projection that scores the next token.
- Vocabulary changes: when you add tokens during fine-tuning, you must resize the embedding matrix (for example
model.resize_token_embeddings(len(tokenizer))) so each new ID has a row. - Memory: for small models the embedding matrix can be a large share of all parameters.
LimitationsCommon mistakes and traps
bank gets one input vector whether it means a river bank or a financial bank. Disambiguation happens in the transformer layers.Mistakes to avoid
- Doing arithmetic on token IDs
- Believing a freshly built embedding layer already "knows" words
- Expecting the input embedding alone to capture sentence meaning
Correct mental models
- ID = address; embedding = learned content at that address
- Lookup = reading learned parameters, not learning
- Context is added by the transformer, not by the lookup
ExplainFeynman Challenge: why can't the AI use token IDs directly?
Token IDs are like call numbers on library books. The number 3797 tells you which shelf to visit, but it says nothing about the book. The embedding is the book you bring back: a long list of numbers the model has learned that describes how the token behaves.
Try explaining this to someone right now: "Why can't a transformer work directly with token IDs, and what exactly happens between tokenization and the first transformer layer?"
🚫 Common Misconceptions to Correct
- Misconception: a bigger ID means a more important word.
Reality: IDs are labels. Importance or similarity is expressed, if at all, by the vectors. - Misconception: the embedding lookup does computation.
Reality: It is a constant-time row read. The learning happened earlier, during training. - Misconception: after tokenization the model already understands the sentence.
Reality: After tokenization it has identifiers; after embedding it has vectors; only after the transformer layers does it have context-aware representations.
BuildMini-project and summary
🎯 Four Things to Build for Mastery
1 — Lookup layer
Implement class Embedding with a random [V, D] list-of-lists and a forward(ids) that returns rows. Compare with nn.Embedding shapes.
2 — ID-vs-vector report
For 20 word pairs, print ID gap and cosine similarity side by side for a real model. Compute the correlation between the two columns.
3 — Nearest neighbours
Write nearest(word, k) that returns the k tokens whose embedding rows have the highest cosine similarity to a word.
4 — Resize experiment
Add two new tokens to a tokenizer, resize the model's embeddings, and inspect the new rows. What values do they start with?
📌 Summary — Everything in Six Bullets
- IDs identify, vectors represent. Tokenization yields integers; the transformer needs numeric vectors.
- Lookup, not computation. Token ID i selects row i of the embedding matrix
Eof shape[V, D]. - IDs carry no usable geometry. The size of an ID or the gap between two IDs means nothing.
- Knowledge lives in learned weights. The embedding matrix and transformer weights come from training; the lookup merely reads them.
- Token embeddings are context-free. The same token gives the same input vector in every sentence.
- Pipeline: Text → Token IDs → Embedding vectors → Transformer computations → Contextual representations.