Attention Scores
Computing Attention Scores: Query × Key Dot Products and Softmax Normalization
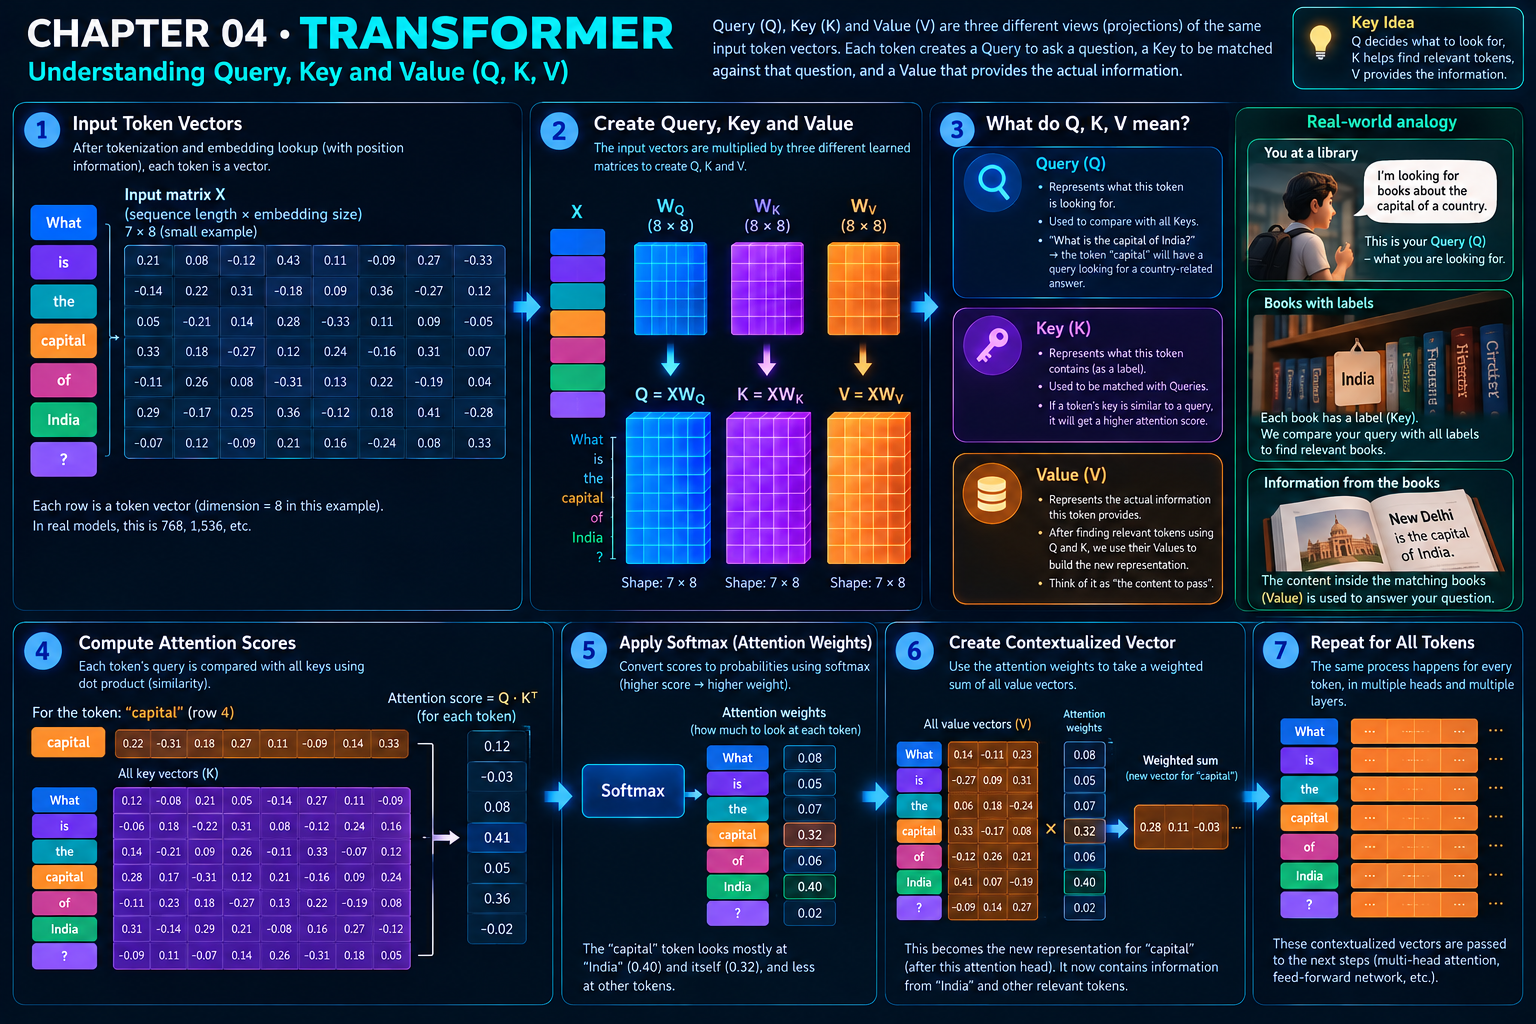
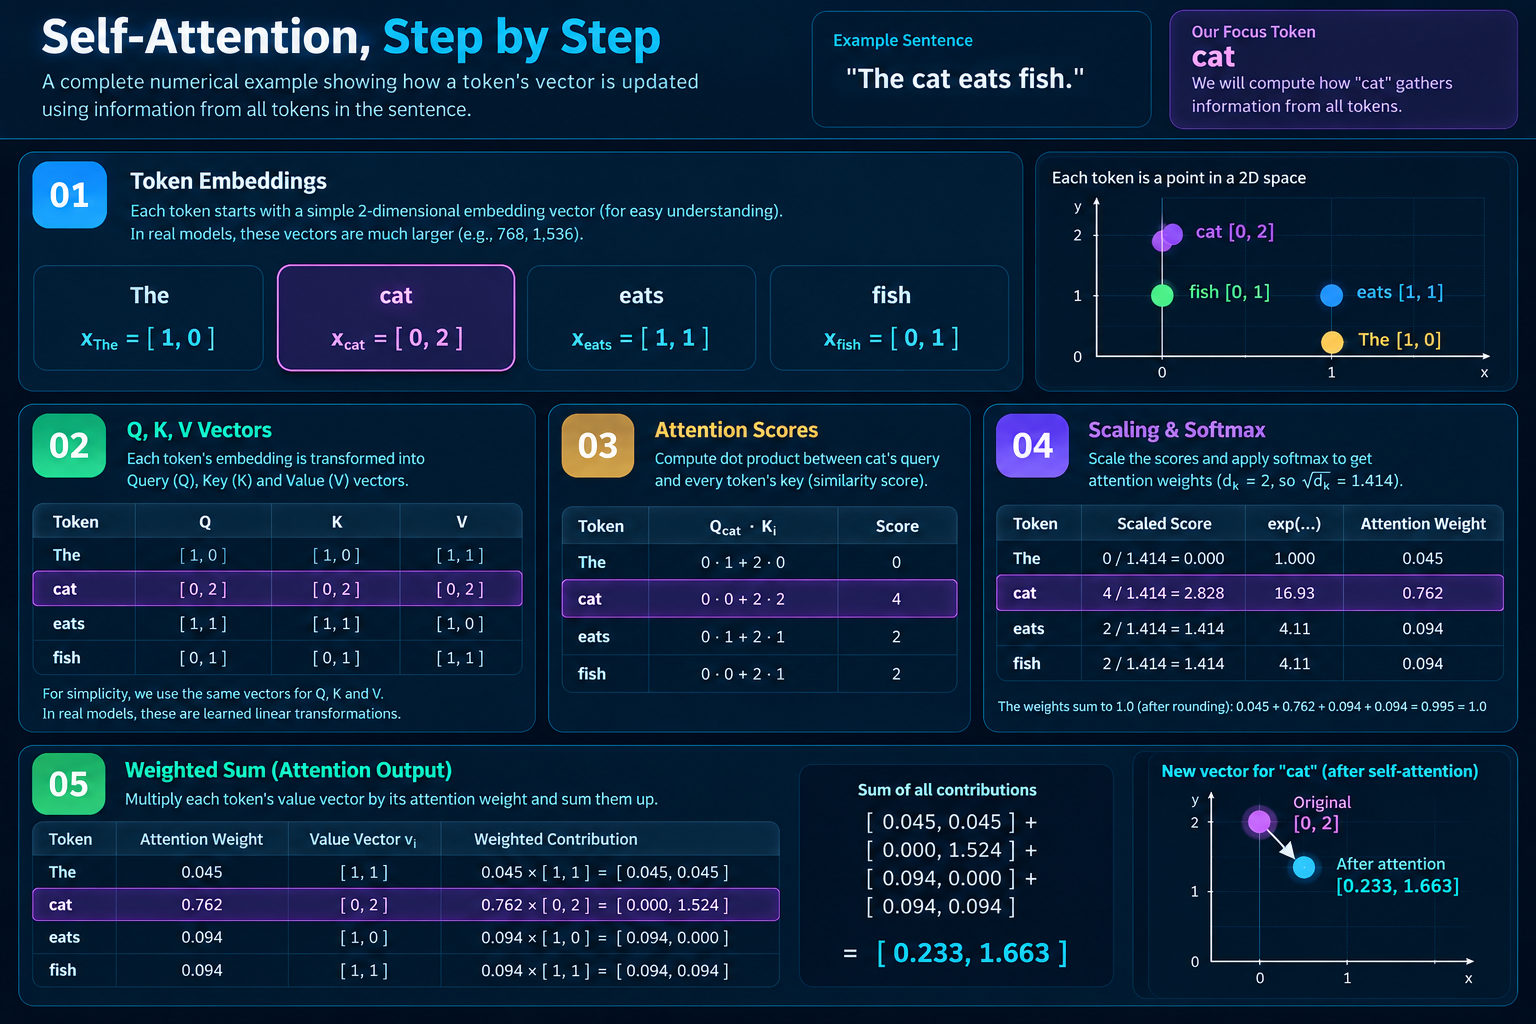
Observe step 4 and 5 below: Raw dot products measure similarity between tokens, and Softmax turns them into positive percentage weights summing to 1.0.
Self-Attention, Step by Step: "The cat eats fish."
Follow the token cat through all five steps: embeddings → Q, K, V → attention scores → scaling and softmax → weighted sum.
What is Attention Scores? Why does it exist? Where does it appear in Self-Attention?
Draw or describe a visual model of Attention Scores. What does it look like conceptually?
Work through a concrete manual example of Attention Scores with real numbers or pseudocode.
Implement Attention Scores from scratch in Python. Keep it minimal — just enough to see it work.
Try Attention Scores on a real example. Vary the inputs and observe what changes.
How is Attention Scores different from related concepts in Self-Attention? What are the trade-offs?
Explain Attention Scores in plain language using an analogy. Could a non-expert follow it?
Build a small project or demo that uses Attention Scores as a core component.
🔨 M-05 MultiHeadAttention 🔁 self-attention → state history design → return to
agent/state_tracker.py
📋 full plan →