Why Transformer?
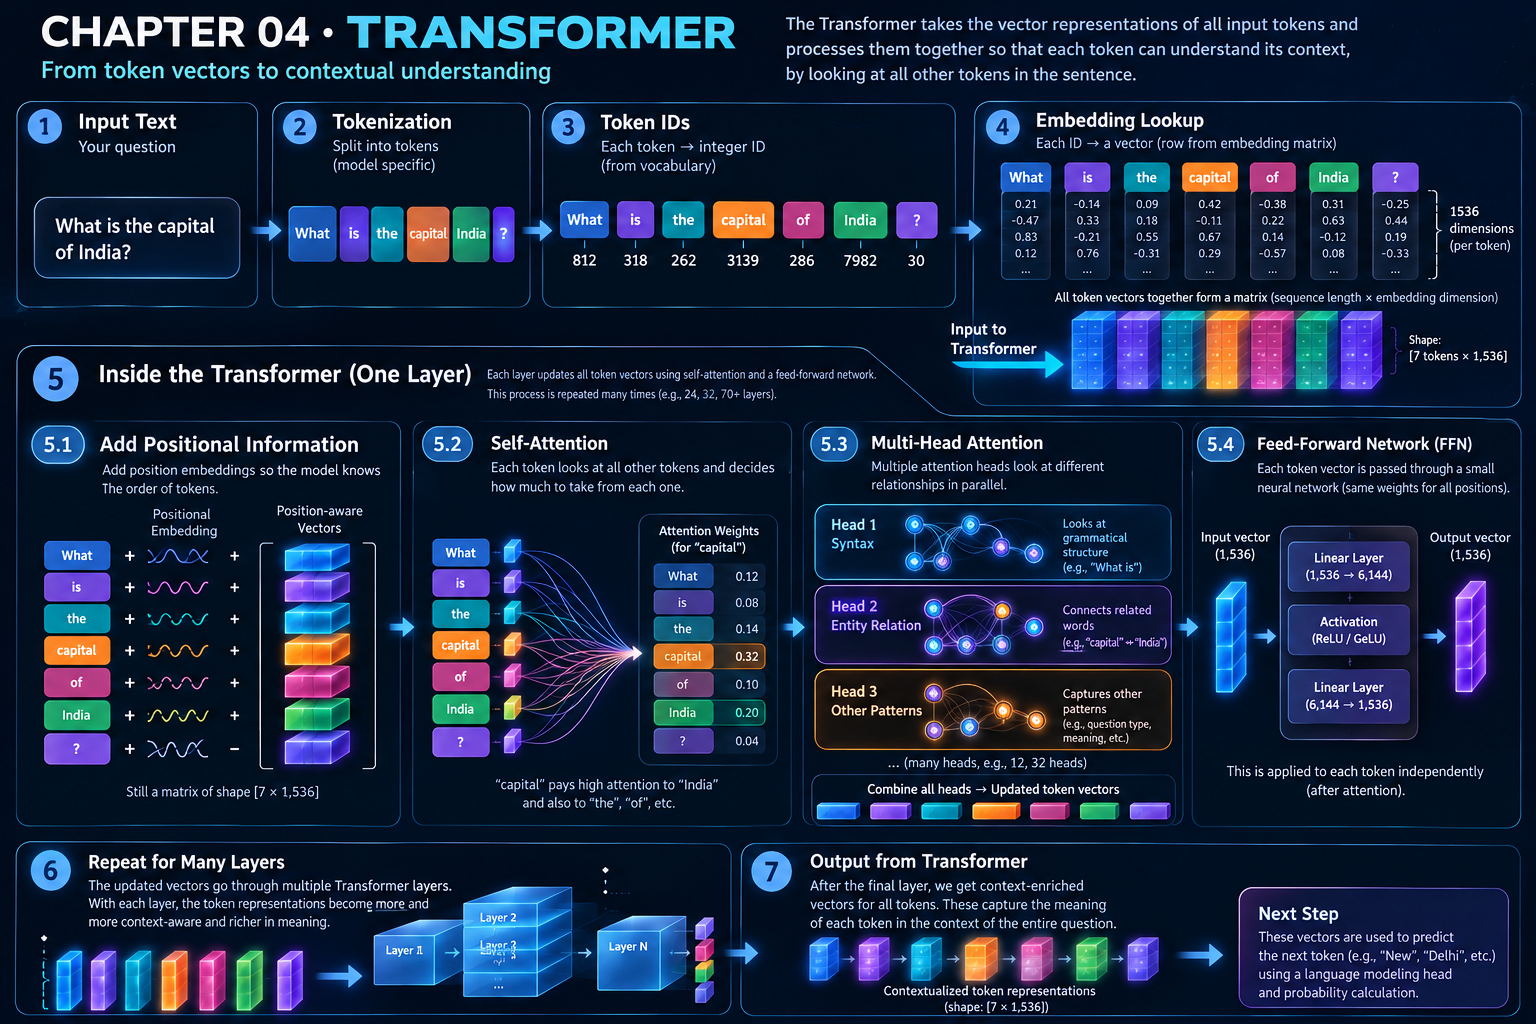
Transformer: From Token Vectors to Contextual Understanding
Why did the Transformer replace sequential RNNs? Because it processes all tokens simultaneously in parallel, using Multi-Head Attention to connect syntax and entities instantly.
What is Why Transformer?? Why does it exist? Where does it appear in Transformer?
Draw or describe a visual model of Why Transformer?. What does it look like conceptually?
Work through a concrete manual example of Why Transformer? with real numbers or pseudocode.
Implement Why Transformer? from scratch in Python. Keep it minimal — just enough to see it work.
Try Why Transformer? on a real example. Vary the inputs and observe what changes.
How is Why Transformer? different from related concepts in Transformer? What are the trade-offs?
Explain Why Transformer? in plain language using an analogy. Could a non-expert follow it?
Build a small project or demo that uses Why Transformer? as a core component.
🔨 M-05 transformer.py 🔁 residual pattern → execution checkpointing → return to
tiny_llm/transformer.py
📋 full plan →