Parameters
💡 Intuitive Mental Model
Did you ever think what a model actually means by "These Many Parameters"?
When an AI announces it has 7 Billion (7B) or 70 Billion (70B) parameters, it is not an abstract magic score. A parameter is simply one single decimal weight ($w$) stored in a matrix on the GPU.
The Core Foundation: Parameter Count = Dimension × Tokens + Layer Projections
- 1. The Embedding Dictionary: Size =
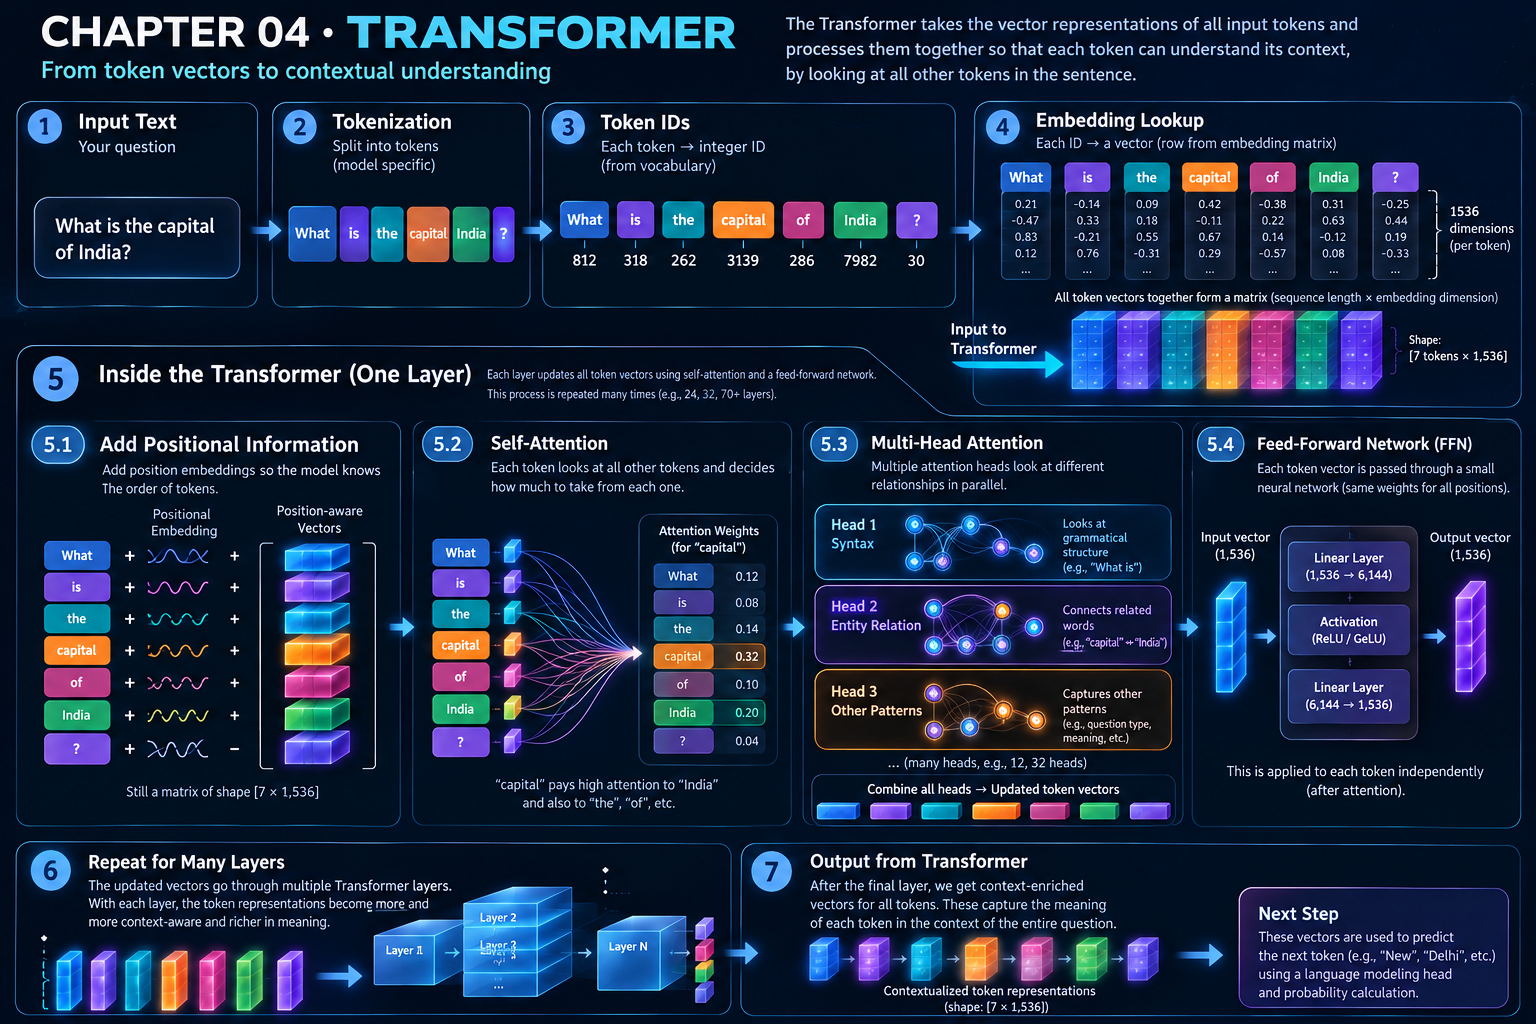
Vocabulary Tokens × Embedding Dimension. For a 32k vocab and 4,096 dimension model, this single matrix is $32,000 \times 4,096 =$ 131 Million parameters. - 2. Transformer Multi-Head Attention: Four projection matrices ($W_Q, W_K, W_V, W_O$) each of size $D \times D \implies 4 \times 4096^2 \approx \mathbf{67\text{ Million parameters}}$ per layer.
- 3. Feed-Forward Network (FFN): Expands $D \to 4D \to D$, contributing $\approx 8 \text{ to } 12 \times D^2 \approx \mathbf{134\text{ to } 200\text{ Million parameters}}$ per layer.
- 4. Total Stacking: $32 \text{ Layers} \times \approx 200\text{M} + \text{Embeddings} \approx \mathbf{7\text{ Billion parameters}}$.
Study this using 4 phases
01
Understand
What is Parameters? Why does it exist? Where does it appear in LLMs?
02
Visualize
Draw or describe a visual model of Parameters. What does it look like conceptually?
06
Compare
How is Parameters different from related concepts in LLMs? What are the trade-offs?
07
Explain
Explain Parameters in plain language using an analogy. Could a non-expert follow it?